Local
A Blueprint for Evaluating AI in Public Administration | Stanford HAI
Meet in Common connects news with real conversations. Use ThinkMatch to arrange a Roundtable and meet people to discuss this story.
Source: Stanford HAI
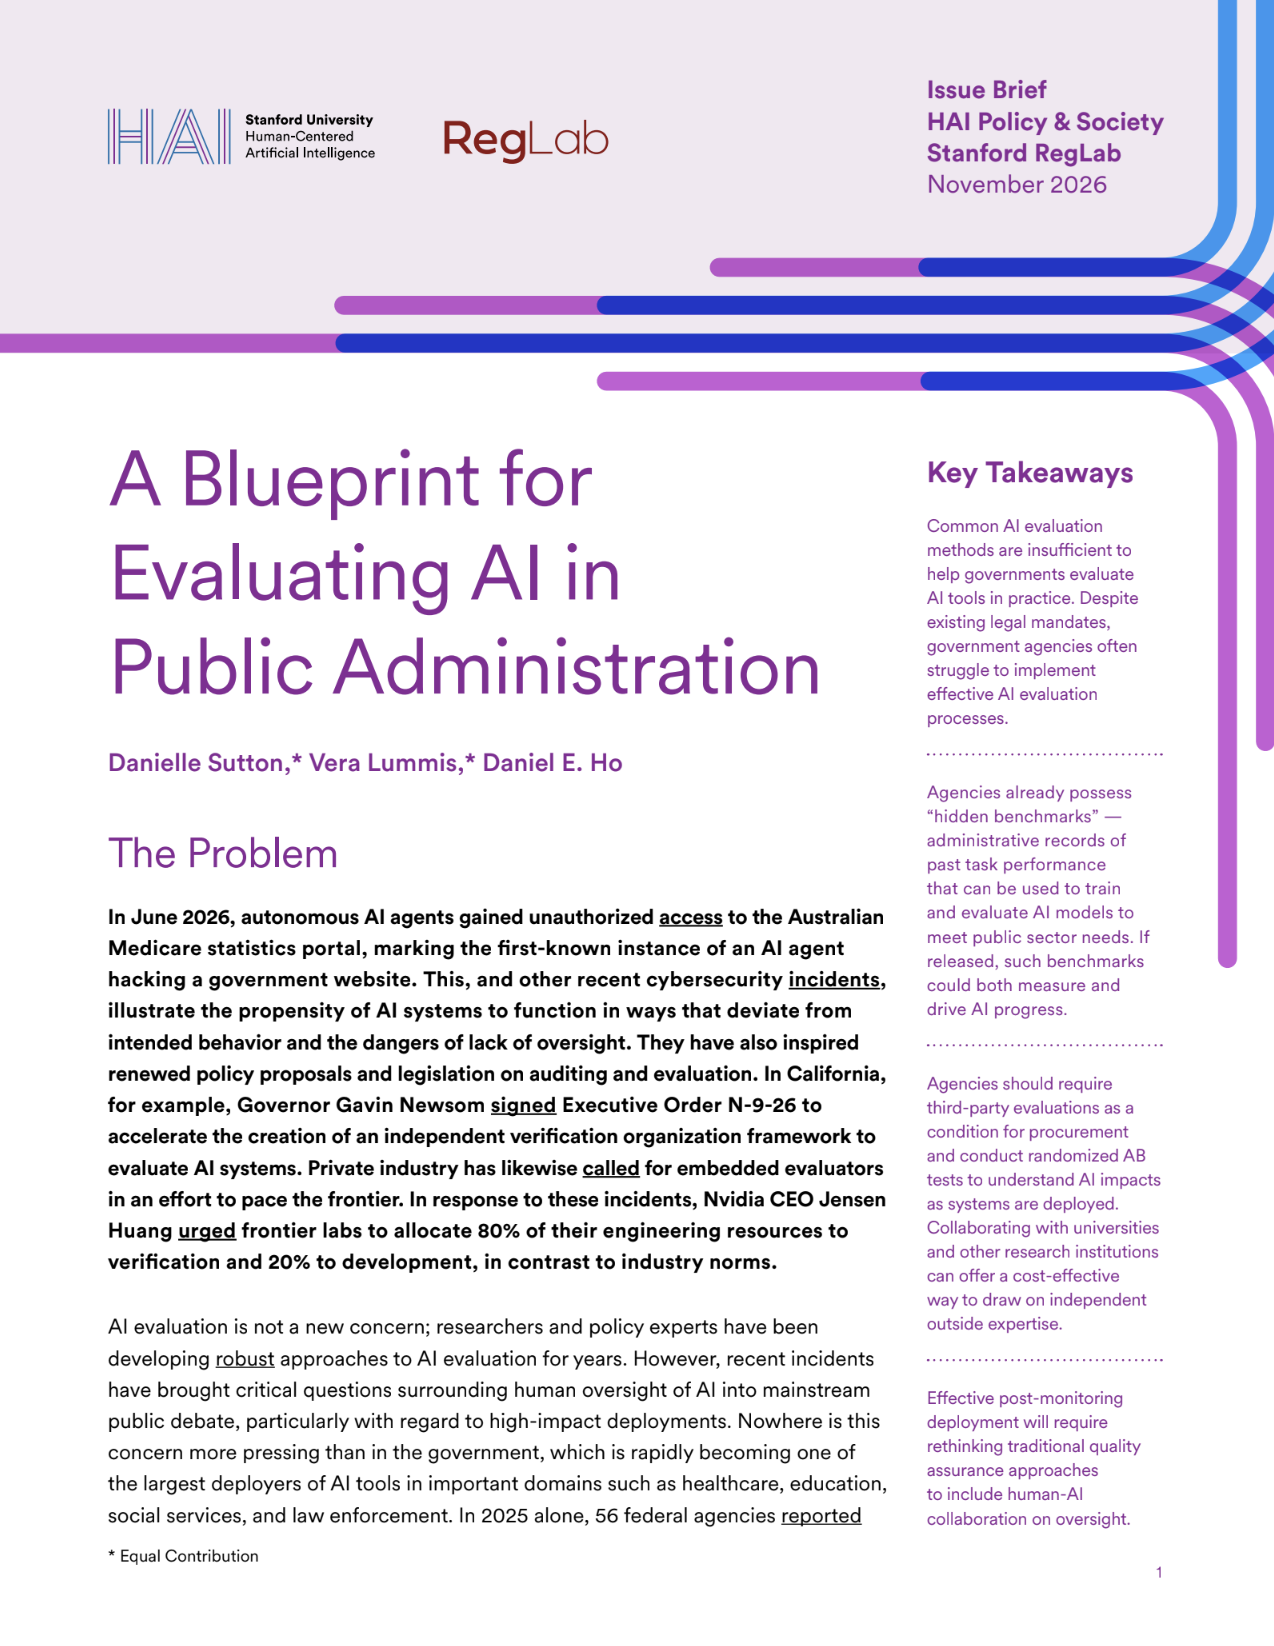
This brief presents a blueprint for how government agencies can effectively evaluate AI tools in high-stakes public services. In collaboration with Key Takeaways Common AI evaluation methods are insufficient to help governments evaluate AI tools in practice. Despite existing legal mandates, government agencies often struggle to implement effective AI evaluation processes. Agencies already possess “hidden benchmarks” — administrative records of past task performance that can be used to train and evaluate AI models to meet public sector needs. If released, such benchmarks could both measure and drive AI progress. Agencies should require third-party evaluations as a condition for procurement and conduct randomized AB tests to understand AI impacts as systems are deployed. Collaborating with universities and other research institutions can offer a cost-effective way to draw on independent outside expertise.
This excerpt comes from the named source. Read the original for the full reporting.
Read the original at Stanford HAI